From Brand PDF to Agent-Readable Specification Without Rebuilding Your Guidelines
Transform your brand PDF into machine-readable rules without starting from scratch.
The brand layer for agents is an authoritative, machine-consumable specification that gives AI tools the values, rules, examples, and context they need to stay on brand without constant manual prompting. Turning a brand PDF into that specification means changing how the guidance is arranged while keeping what it says. Model Context Protocol lets agents that support it use the same source, while ownership and versioning keep that source up to date.
Why brand PDFs fail when AI agents try to apply them
A brand PDF was built for human interpretation, while an agent needs rules it can apply to a task. A designer reads “warm but expert tone” and calibrates against campaigns they have seen. An agent has only the words it receives. The phrase describes an intention without defining the choices that would make a particular sentence acceptable. That gap leaves the agent to infer what the brand means.
Often, the guidelines never reach the agent at all. The brand book sits in a shared drive while someone types “write an Instagram post for us” into a tool. Even when the document is supplied, its internal inconsistencies can undermine it. A rule duplicated in two places may have drifted, so the agent applies whichever version it reads first. A reference to a missing document invites improvisation, while the absence of rejected work and its rationale leaves corrected mistakes available to repeat.
These failures compound as the volume of generated content grows. Colors look slightly off, the words sound less like the brand, and visual styles pull in different directions. Ambiguity scales with the output it informs. The model is filling gaps in incomplete information, which makes the failure architectural.
What "agent-readable" actually means — and what it does not require
Making guidelines agent-readable means putting each kind of rule in a format that fits how it will be used. A color is measured, a tone is judged, and an image right is checked against a contract. They require different kinds of evidence and instruction. Filing them together in a PDF does not make those distinctions explicit to an agent. Separating them by format preserves the substance while making the conditions for applying it clearer.
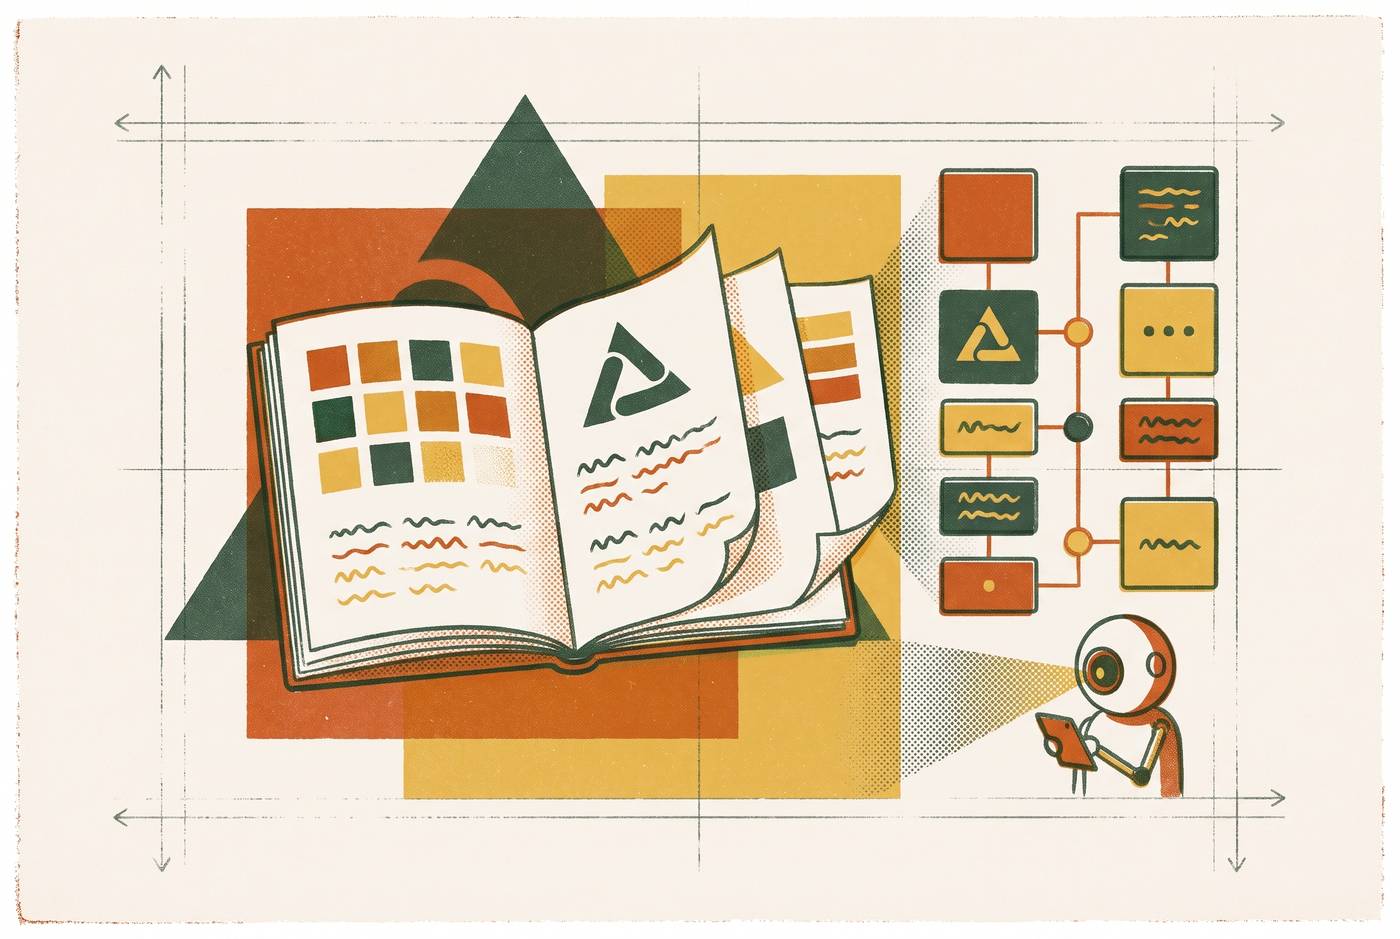
The existing PDF can remain useful to people who design and print. The structured specification serves the tools that write, generate, and review. It translates brand judgment into named values an agent can retrieve, behavioral rules it can test against output, and examples that explain corrections to prohibited phrases. The starting material is the guidance the team already has.
Existing tools support parts of this transformation. Figma variables can export to the DTCG format, while plain-text or Markdown files can hold voice and messaging rules. Both can be used without turning the whole brand book into software. Some information needs to be exact, and some guidance needs to be explained. As those inputs become clear, teams move from checking finished content toward setting rules for what agents use before they generate it.
The four-layer structure that covers every kind of brand rule
The first layer is design tokens for measured values, including colors, typefaces, logo clear space, and spacing. Each token has a name, a type, and a value, with usage context where needed. The name stays the same so the token can always be found. A primary color may appear as a Pantone in the PDF, a CMYK value in the print specification, and a hex value in CSS. An authoritative token resolves that ambiguity by making the relevant value and its intended use explicit.
The W3C Design Tokens Community Group put out its first stable specification on October 28, 2025. Its format shows how to encode those values. Usage context can identify approved media and tolerated color deviation measured in ΔE. Around 1 is barely visible, while a threshold of 2 allows small export variations through while catching the “almost the same” blue. To begin without a developer, use a plain table containing the name, screen value, print value, usage, and media restrictions.
The second layer is behavioral prose for tone, positioning, and recurring phrasing. “Friendly and professional” gives an agent little to test. More executable rules include “keep most sentences short,” “use no more than one exclamation mark,” “address the reader as ‘you’,” and “avoid absolute claims like ‘the best’ or ‘number one’.” Recurring categories can be equally explicit, with short canonical answers for facts, exact phrases for pricing, and headline-first wording for policies.
To prevent those rules from diverging, keep one file per topic and point to it everywhere else. Topics can include identity and positioning, tone, a blacklist, and key messages. A compact AI persona block can combine one short paragraph with a do-and-don’t list for a system prompt. An engineer or prompt author can use that block to guide tone without needing the whole section that describes it.
The third layer is approved and rejected examples with reasons. Pair prohibited wording with a correction and its rationale. For example, “Revolutionize your communication” is rejected as hype vocabulary with no proof, with the corrective direction “say what changes, with a number to back it up.” The reason helps an agent use what it learned with other phrases too.
For each channel type, show three to five “this is us” examples and two to three “this is not us” examples. Keep a living rejections file containing the excerpt or image, the rule broken, and the correction, and add to it during each review cycle. A rejection without a reason is a silent signal. The file preserves the judgment that would otherwise disappear after the reviewer fixes the output.
The fourth layer is context files and schema for AI systems. With plain-text or Markdown files, rules can be used in project knowledge, custom instructions, or brand kits. Separate them by function, including voice, messaging, ideal customer profile, company facts, and offerings. Named files support retrieval of the context a task needs. Structured JSON-LD schema, including FAQPage, Product, HowTo, and Organization, serves a related purpose on key pages by helping answer engines attribute and summarize brand content correctly. Keep answer text in schema identical to the page text so that these surfaces do not contradict each other.
How to audit existing guidelines before restructuring them
Before encoding rules, audit what customers and prospects can actually see. Pull website pages, paid ads, social posts, emails, sales decks, proposal templates, product one-pagers, and executive presentations. Check how those assets fit with what the brand says it stands for. The current market presence is the starting point. Writing a specification for an idealized brand while live materials keep fragmenting would preserve the discrepancy.
Visual drift includes multiple logo versions, old colors, improvised slide layouts, and inconsistent icon styles. Verbal drift occurs when the homepage sounds premium but sales emails sound casual and social posts sound like another company. Channel drift occurs when those channels are held to different standards. Asset drift comes from old files that people still share in shared drives, agency folders, or local desktops.
Then resolve authority before transforming the material. If a team cannot locate the current approved logo, template, or tagline in under a minute, the weakness is governance. When a sales deck and website describe a product differently, designate the authoritative source before encoding either description. Retire outdated material explicitly and check that every document cited in existing instructions exists and has a named owner. Retrieval alone is not a quality test. A system that quickly finds and reuses words the brand stopped using two years ago makes the problem worse.
How can multiple AI agents access the same brand rules through MCP?
A structured specification governs an agent only when the agent can reach it. Model Context Protocol lets tools that support it look up brand knowledge in a live source before they generate content. Anthropic open-sourced MCP on November 25, 2024. By 2026, its ecosystem includes Claude, ChatGPT, Gemini, Cursor, Visual Studio Code, and agent frameworks and servers.
An MCP server can expose voice rules, visual identity, positioning, and do’s and don’ts for tools to consult. Instead of depending on what a model may have absorbed during training, the agent can retrieve the context relevant to the current task. This changes the role of the specification from a document someone must remember to paste into a prompt to a source available within the workflow.
Concrete uses show how that access works. Claude can call an MCP-connected image generation tool with the prompt, brand context, and resulting asset in the same thread. Notion and Google Drive MCP servers can also let Claude look up an ideal customer profile document, a brand voice profile, and a content calendar by name. Manual transfer between tabs is no longer necessary for those retrievals.
Brand knowledge may remain scattered across Figma, a CMS, a DAM, Notion, and decks, with conflicting versions reachable through the same interface. The audit’s authority decisions therefore remain essential. MCP combined with a designated authoritative source addresses the version conflict, while connectivity alone does not. In the broader workflow of design, structured data, distribution, building, governance, and improvement, the four-layer specification supplies the structured data that the rest of the process uses.
Keeping the specification current as the brand evolves
A specification becomes stale when a brand change fails to reach the agents using it. Positioning changes, products are retired, claims change after legal reviews, and campaigns bring in new visual styles. Each change can affect a different layer. Without versioning and propagation, agents work from whatever they last received, leaving them with outdated information. The original PDF problem then returns in a more structured format.
Every “no, not like that” may reveal a missing rule or a qualification to an existing one. Record the reason and add it to the layer it belongs in so it goes beyond a lone review comment. Corrections should improve the source. Over time, this makes the specification more precise about the distinctions that human reviewers already enforce.
Products are also treating brand information as live context. Canva announced in February 2026 that Brand Kits containing colors, fonts, layouts, and logos can be used directly inside ChatGPT and Claude. Figma’s brand guidelines generator connects to the libraries and design tokens already in use, keeping guidance in line with the actual design system instead of a separate document that shows an ideal version. These approaches reduce separation between guidance and working assets. They illustrate why a specification needs an ongoing connection to the systems in which the brand changes.
To sustain that connection, name an owner for each layer and define review triggers, including product changes, legal updates, and campaign launches. Clearly mark old material as retired and remove it from beside the approved version. This is infrastructure work. Making the brand machine-readable does not hand its identity over to machines. People still define what the brand stands for, and the specification lets that judgment scale across the agents that apply it.